

Today’s guest post was contributed by Nele Haelterman, assistant professor at Baylor College of Medicine’s molecular and human genetics department. Nele combines team science, genetics, and neuroscience to study the mechanisms that drive joint pain. Nele is passionate about science communication and advocacy: she runs a blog for early career scientists (ecrLife) and promotes open, reproducible science (reproducibility 4 everyone). You can follow Nele on LinkedIn.
When you talk to scientists about standardizing an aspect of their data-related or experimental workflows, you can almost hear their collective internal groans. Most researchers greatly prefer being at the bench to test their next hypothesis compared to sitting behind a computer, completing spreadsheets to make sure their dataset complies with the most current standard. At the same time, researchers also aspire to generate findings and knowledge that can provide new scientific insights.
Advancing scientific knowledge requires researchers to be able to reproduce, compare, and build on each other’s findings. Standardization provides the foundation for this process, allowing us to compare and integrate data, and hence findings, across studies. It does this through the development and use of harmonized methods, workflows, and reporting criteria that make sure data are generated, processed, and described in consistent ways, regardless of where it was generated. Standardization ensures we all use the same names for the same tissue types, cells, genes, etc (terminology, ontology). In addition, it makes sure each shared dataset is accompanied by a complete description of how it was generated (metadata). Annotating datasets so they contain all of this information can be quite tedious, forming the basis of researchers’ mixed feelings about standards. However, as data generation speeds up across labs, standardization is the engine that will drive integration and innovation into the future.
Understanding the importance of consistent genome assembly and annotation for enabling direct comparisons across genomes and species, geneticists and genomicists have long been leaders in developing and adopting community standards. Despite these efforts, several significant gaps remain. For example, while de novo genome assembly based on long-read sequencing has become increasingly accessible to individual research groups, no consensus exists on the (meta)data that should be included in arthropod genome reports. Consequently, answering seemingly straightforward questions about your favorite gene’s evolutionary history can become surprisingly challenging.
To overcome this problem and catalyze the development of a community standard for arthropod genome reporting, Tvedte et al. reviewed 100 recently published arthropod genome papers for approaches used throughout the study. Reporting on this comparative analysis in the September issue of GENETICS, the team found broad consensus in genome assembly approaches and reported quality metrics across studies. In contrast, the projects displayed substantial variation in other key stages, including sample processing and sequencing, genome annotation, and others. In addition, the authors discovered that genome annotations were often not deposited in publicly accessible repositories, greatly reducing the reusability of the newly published genome. Together, the authors identified several opportunities for developing community standards and policies that would make arthropod genome resources more comparable and would greatly increase their long-term value for comparative and applied research.
References
Tvedte ES, Bucher G, Luecke DM et al. Toward standardization in arthropod and biodiversity genome projects. Genetics, Volume 234, Issue 1, September 2026, iyag172. https://doi.org/10.1093/genetics/iyag172

Guest posts are contributed by members of our community. The views expressed in guest posts are those of the author(s) and are not necessarily endorsed by the Genetics Society of America. If you'd like to write a guest post, e-mail communications@genetics-gsa.org.
View all posts by Guest Author »Read more in
-

Thank you, GSA community!
Thank you for being a member of the Genetics Society of America! As GSA’s current president, I am writing to tell you about Society projects and initiatives that we hope you will find useful in advancing your science and your career. Scientific research is a collaborative and exciting endeavor. Scientific societies like GSA exist to…
-

Where are they now? Rosalind Franklin Young Investigator Award recipients share updates on their research
Rosalind Franklin Young Investigator Award applications are open–make sure you submit your application or nomination of a colleague by September 30, 2024.
-

University of Minnesota researchers map genome of the last living wild horse species
The study, published in G3: Genes|Genomes|Genetics, is part of larger conservation efforts to save Przewalski’s horse.
-

Congratulations to the Spring 2024 DeLill Nasser Awardees!
GSA is pleased to announce the recipients of the DeLill Nasser Award for Professional Development in Genetics for Spring 2024! Given twice a year to graduate students and postdoctoral researchers, DeLill Nasser Awards support attendance at meetings and laboratory courses. The award is named in honor of DeLill Nasser, a long-time GSA supporter and National Science Foundation…
-

Carolyn Damilola: an NFS Rising Scientist on a lifelong quest to learn more
Carolyn Damilola is an NFS Rising Scientist from Nigeria doing respiratory system research and paving the way for scientists from underrepresented communities through mentorship.
-
What does a good microgrant proposal look like?
Members of the Microgrant Review Committee share their tips for a successful proposal.
-

The first piece of the facial recognition puzzle
New research in GENETICS gives a first peek at the molecular pathway involved in recognizing faces.
-

New Senior Editor Amy MacQueen joins GENETICS
A new senior editor is joining GENETICS in the Genome Integrity and Transmission section. We’re excited to welcome Amy MacQueen to the editorial team.
-

Block party on the zebrafish sex chromosome
Research in G3 identifies a gene regulatory block of the zebrafish genome responsible for overseeing the maternal-to-zygotic-transition.
-

Unraveling the mysteries of duckweed: epigenetic insights from Spirodela polyrhiza
Research published in G3 offers insight into the impact of DNA methylation on clonal propagation in asexually reproducing plants.
-

A microbiologist’s quest to understand CRISPR in bacterial self-defense
2024 Genetics Society of America Medal recipient Luciano Marraffini determined how CRISPR-Cas systems destroy genetic targets with precision, paving the way for gene editing technology development.
-
Unlocking mysteries of trait and disease heritability in dogs
2024 Edward Novitski Prize recipient Elaine Ostrander, a pioneer of the domestic dog model, discovered numerous genes affecting dog size, morphology, behavior, and disease susceptibility—many of which have relevance in humans.
-
GSA and collaborators Personal Genetics Education & Dialogue and Reclaiming STEM Institute launch NSF-funded BIO-LEAPS project to support culture change in genetics
We are thrilled to announce that the Genetics Society of America (GSA) is collaborating with the Personal Genetics Education & Dialogue (PGED) based in the Department of Genetics at Harvard Medical School, and the Reclaiming STEM Institute (RSI) on a Leading Culture Change Through Professional Societies of Biology (BIO-LEAPS) grant from the U.S. National Science…
-

Daman Saluja: Navigating Science and Policy in India
In the Paths to Science Policy series, we talk to individuals who have a passion for science policy and are active in advocacy through their various roles and careers. The series aims to inform and guide early career scientists interested in science policy. This series is brought to you by the GSA Early Career Scientist…
-
A fly geneticist’s journey into discovering rules of organ development
2024 George W. Beadle Award recipient Deborah Andrew discovered new genes and pathways in Drosophila salivary gland organogenesis. Now, her work can help optimize cell secretion in therapeutic applications and fight malaria.
-
Małgorzata Gazda: How receiving the DeLill Nasser Award helped her land her dream job
Have you ever experienced an event that changes the course of your life, or in this case, your career? Małgorzata (Gosia) Gazda is Assistant Professor at the University of Montreal and in 2022, she received the DeLill Nasser Award for Professional Development in Genetics, which she used to attend and present at the 2022 Population,…
-
Hongyu Zhao joins GENETICS as new Senior Editor
A new senior editor is joining GENETICS in the Statistical Genetics and Genomics section. We’re excited to welcome Hongyu Zhao to the editorial team.
-
GSA Member Julio Molina Pineda Receives DeLill Nasser Award, Shines at TAGC 2024
“At any career stage, the GSA membership is an amazing investment for any genetics professional!” Julio Molina Pineda is a PhD Candidate in Cell and Molecular Biology and a Research Assistant at the University of Arkansas, and a Doctoral Academy Fellow at the Lewis Lab. In 2023, Julio was awarded the DeLill Nasser Award for…
-
In Memoriam: Ellsworth Herman Grell (1932–2023), a pioneer of Drosophila genome engineering and annotation
Ellsworth (Ed) Grell blessed the Drosophila community through three enduring legacies: as a pioneer of chromosome mechanics, as a primary organizer and synthesizer of genetic knowledge in Drosophila, and as a graceful mentor to those fortunate to have known him personally. Ed grew up in rural Nebraska, completed his undergraduate studies at Iowa State, and…
-
Congratulations to the #Fungal24 Poster Award winners!
We are pleased to announce the recipients of the GSA Poster Awards for posters presented at the 32nd Fungal Genetics Conference! Undergraduate and graduate student members of GSA were eligible for the awards, and a hard-working team of judges made the determinations. Congratulations to all! Felicia Ebot Ojong, The University of Georgia My research is focused…
-
Poster presentation tips for TAGC 2024
You’ve been selected to present a poster at The Allied Genetics Conference 2024 in March—you’ve celebrated, made plans to attend, now what? This is an exciting opportunity to showcase your research and engage with fellow members of the genetics community, so you want to make sure you’re prepared. We wanted to offer you some tips…
-
Maximize your TAGC 2024 experience
A guide to all that National Harbor & DC have to offer Are you joining us for The Allied Genetics Conference 2024 in March? Make the most of your #TAGC24 experience in National Harbor! We know the science will keep you busy, but you deserve to unwind and have some fun, so we’ve curated a…
-
Early Career Leadership Spotlight: Sarah Petrosky
We’re taking time to get to know the members of the GSA’s Early Career Scientist Committees. Join us to learn more about our early career scientist advocates. Sarah PetroskyMultimedia SubcommitteeUniversity of Pittsburgh Research Interest I am interested in understanding adaptation that has been happening recently in populations by dissecting the ways that genes underlying an adaptation…
-
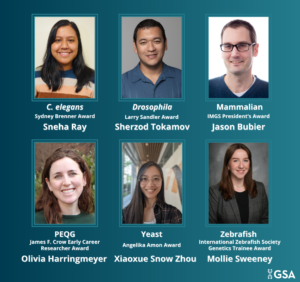
TAGC 2024 Early Career Award Winners
GSA is pleased to announce the winners of the early career awards presented at The Allied Genetics Conference 2024. These awards are specific to particular TAGC communities and recognize early career scientists’ outstanding work on their respective research organisms. The awardees will present their talks in keynote sessions at TAGC 2024. Don’t miss the opportunity…
-
Preeminent geneticists recognized with revamped GSA Awards
In 2022, GSA’s Board of Directors launched an audit to review the five major awards conferred by the Society. Today, we are thrilled to announce the recipients of the reimagined GSA Awards, including the new Genetics Society of America Early Career Medal. The scientists honored this year are recognized by their peers for their outstanding…
-
Fly Board funds outreach programs to spread the word about Drosophila research
In 2020, the Fly Board voted to use part of its reserve fund to support efforts to increase trainee participation as well as equity and diversity in the Drosophila community. An awards committee decides how the money will be spent each year, and from 2020–2022, the committee posted a very broad call for applications from…
-
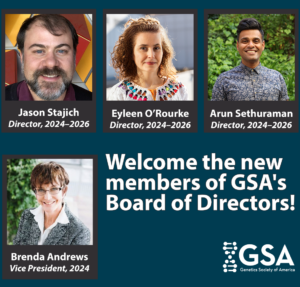
New members of the GSA Board of Directors: 2024–2026
We are pleased to announce the election of four new leaders to the GSA Board of Directors: 2024 Vice President/2025 President Brenda Andrews Professor, University of Toronto It’s an honor to continue my association with the Society by serving as Vice President of the Board of Directors. I have broad knowledge of the ongoing activities…
-

Early Career Leadership Spotlight: Samuel Isife
We’re taking time to get to know the members of the GSA Early Career Scientist Subcommittees. Join us to learn more about members of the Early Career Leadership Program.
-

What happens when you send a letter to Congress?
Ever wonder what happens after you contact your elected officials? Former AAAS-ASGCT Congressional Policy Fellow in the U.S. House of Representatives, Adriana Bankston walks us through the journey of a congressional advocacy letter and explains how scientists can use their voices to help shape research funding and federal policy.
-

Early Career Leadership Spotlight: Faye Romero
We’re taking time to get to know the members of the GSA Early Career Scientist Subcommittees. Join us to learn more about members of the Early Career Leadership Program.